Full-Stack
MERN + AI: Adding LLM Features to a Node/React App
Adding MERN AI features is mostly a full-stack problem wearing an AI hat. The model call is ten lines; the work is deciding where the API key lives, how responses reach the UI without blocking, what happens when the provider times out, and how you store conversations and usage in MongoDB without painting yourself into a corner. I have built this pattern more than once, and the architecture matters more than the model choice.
I'm Sameer Ahmad, an Applied AI Engineer based in Dubai with 7+ years of software development experience, working daily with React, Node.js, Express.js, and MongoDB alongside Python-based AI tooling. This is the setup I use when a client wants LLM features inside an existing MERN app — and it's the same shape as the stack behind my portfolio, which is a Vite + React SPA served alongside a separate static blog.
Where do MERN AI features actually fit in the stack?
The cleanest split keeps the browser dumb about providers:
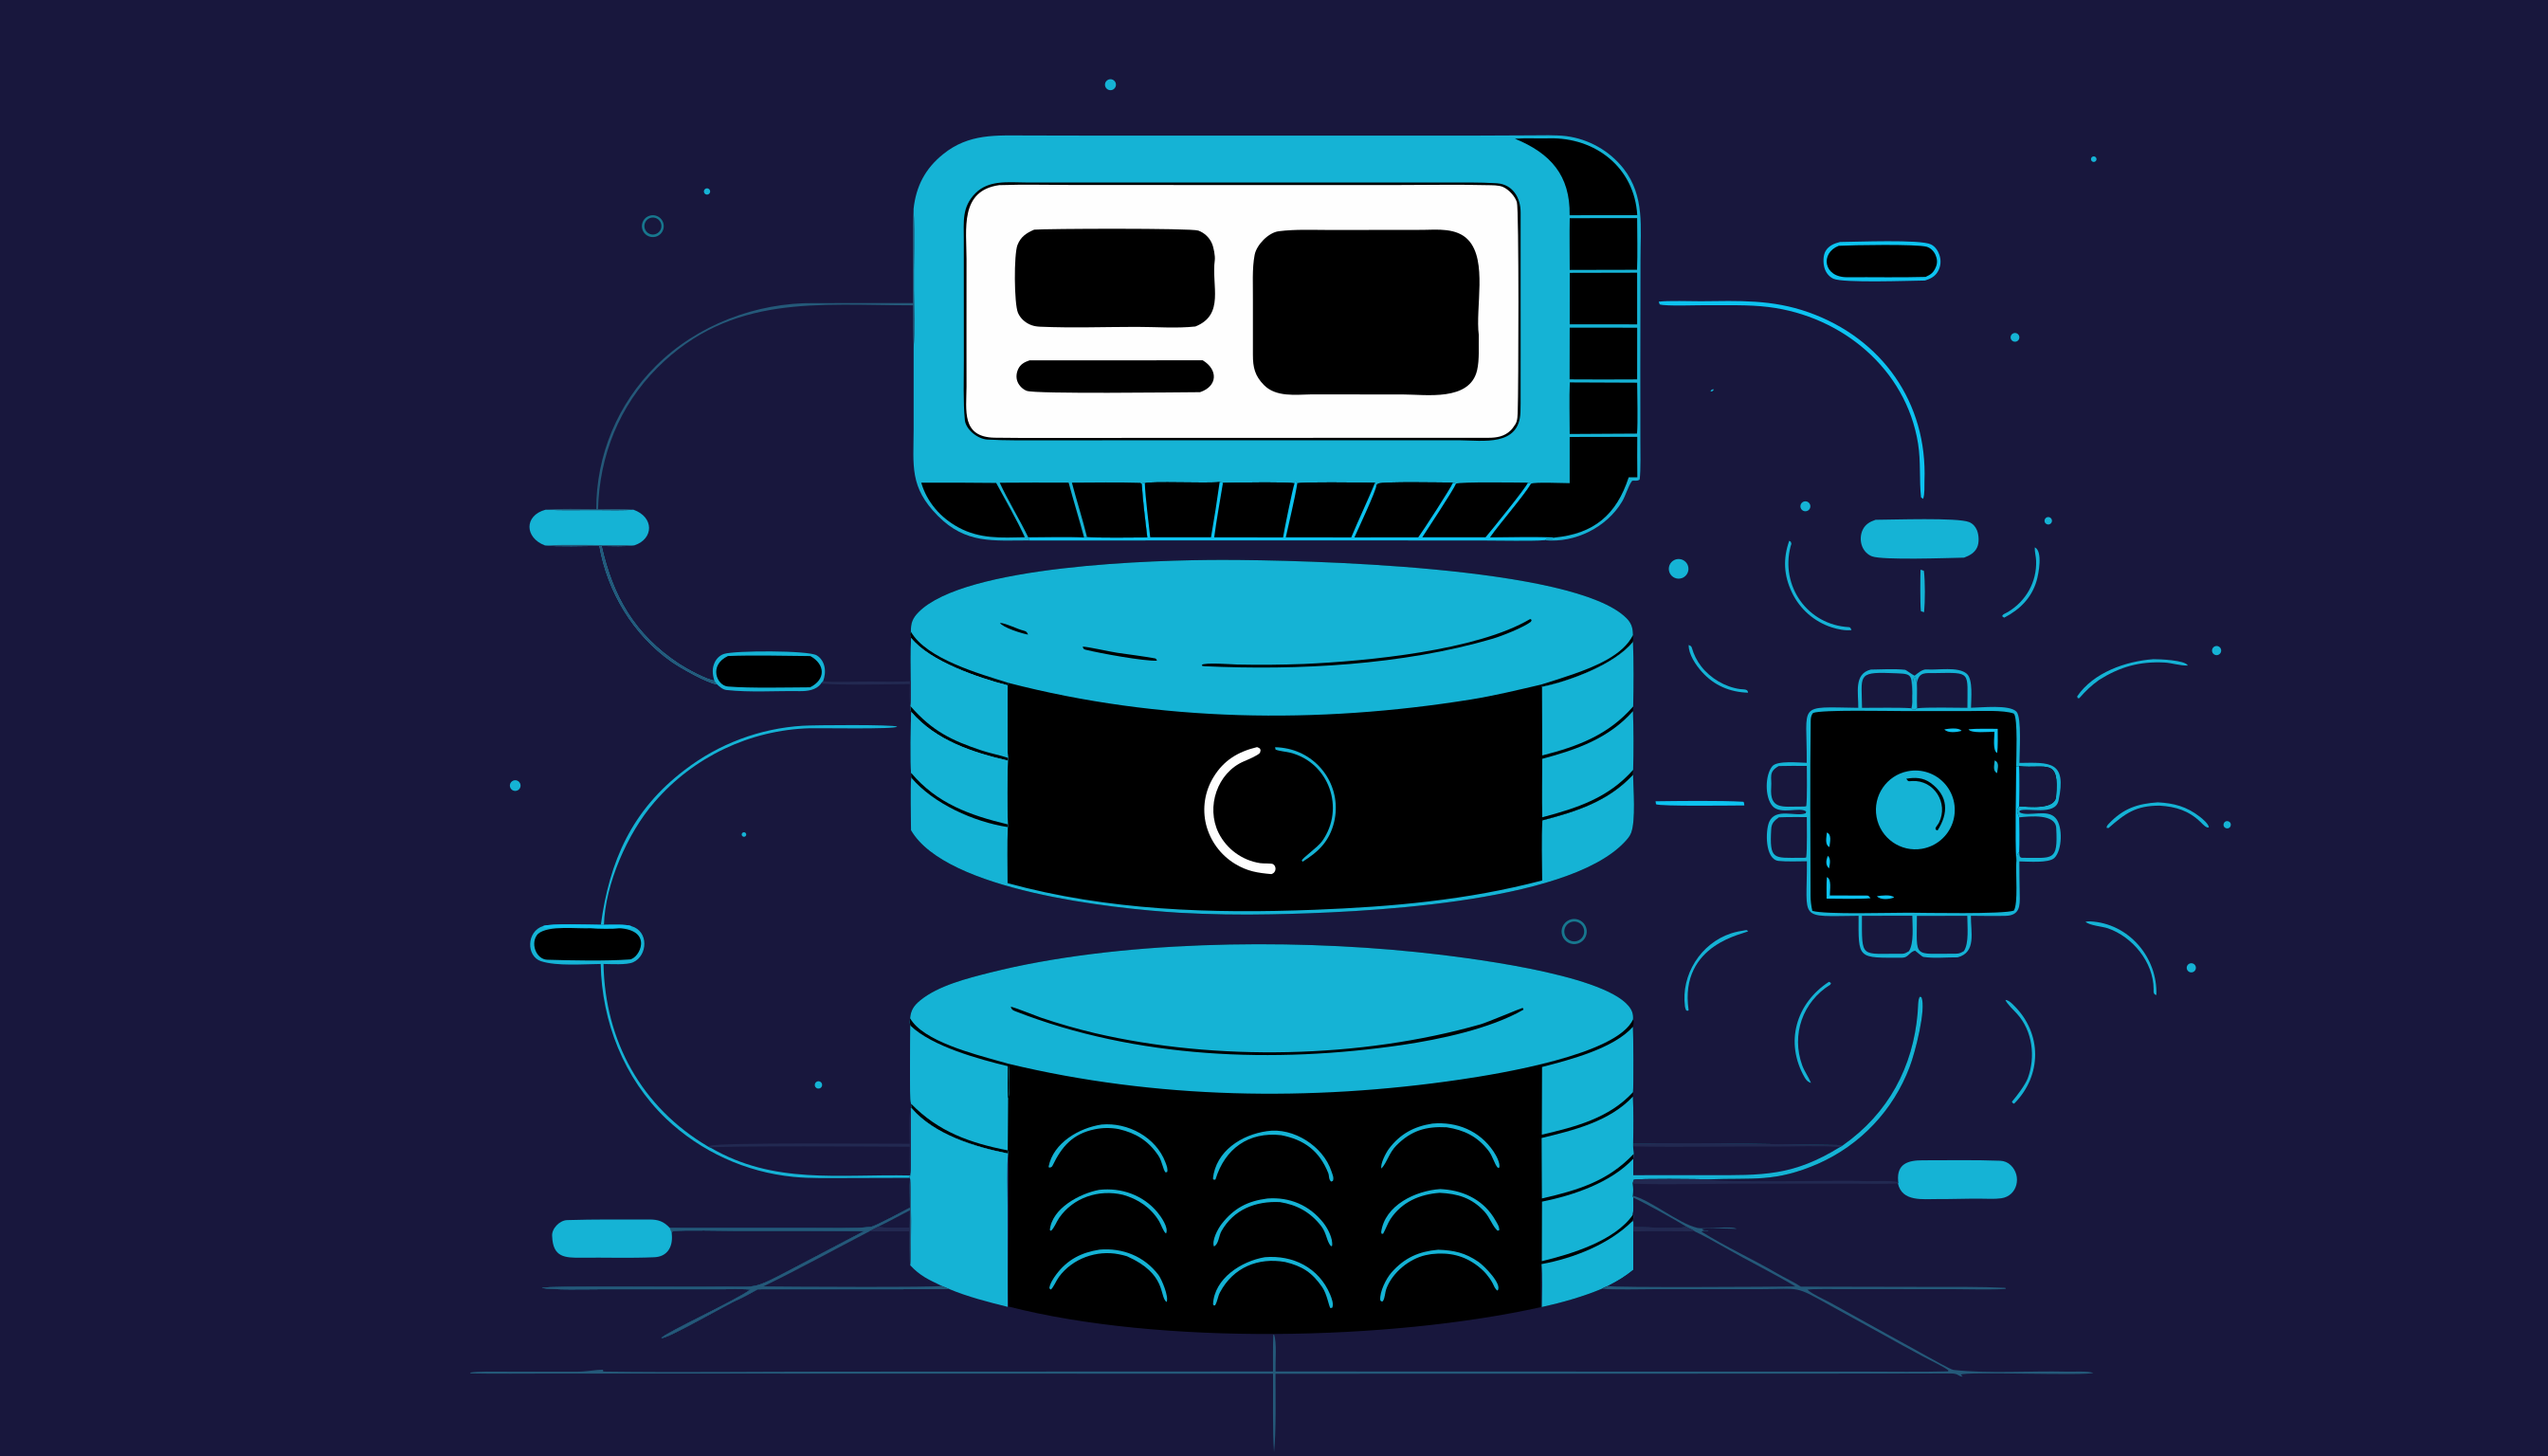
- React owns the conversation UI, streaming display, optimistic states, and abort controls. It never sees a provider API key.
- Express owns the AI surface: one route per feature, provider adapter, retries, timeouts, schema validation, rate limiting, and token accounting.
- MongoDB owns persistence: conversation threads, message history, prompt versions, and usage records per user and per feature.
- The model provider stays behind your adapter, so swapping or routing between providers is a config change rather than a refactor.
That last point is the one people skip. Coupling your React components to a vendor's SDK shape guarantees a rewrite when you change your mind — and you will change your mind.
Designing the Express layer for LLM calls
One route per feature, a narrow request schema, and a hard timeout. A representative shape:
router.post("/api/ai/summarize", auth, validate(summarizeSchema), async (req, res) => {
  const controller = new AbortController();
  const timer = setTimeout(() => controller.abort(), 20_000);
  try {
    const result = await ai.run("summarize", req.body, { signal: controller.signal });
    await Usage.record({ userId: req.user.id, feature: "summarize", ...result.usage });
    res.json({ text: result.text });
  } catch (err) {
    handleAiError(res, err); // maps timeouts, rate limits, bad output to real status codes
  } finally {
    clearTimeout(timer);
  }
});
Three details do the heavy lifting. Feature names route to prompt + model + limits in one place, so changing a model is a config edit. Validation rejects malformed input before it costs a token. Errors map to honest HTTP status codes — 504 for a provider timeout, 429 for rate limits, 502 for unparseable output — so the React side can tell the difference between "try again later" and "your request was wrong."
Everything else about the route is ordinary Express work, which is the point: authentication, per-user rate limits, and request logging behave exactly as they do on your existing endpoints. If you have already built a payments or upload route in this app, an AI route should feel like a third one of those, not a new discipline.
Streaming LLM responses to React without drama
Non-streaming AI endpoints feel broken: a spinner for six seconds, then a wall of text. Express can stream the model's output straight through with a fetch ReadableStream, and React consumes it with a reader loop:
const res = await fetch("/api/ai/chat", { method: "POST", body: JSON.stringify(payload) });
const reader = res.body.getReader();
const decoder = new TextDecoder();
while (true) {
  const { done, value } = await reader.read();
  if (done) break;
  setDraft((prev) => prev + decoder.decode(value, { stream: true }));
}
Two things make this hold up in practice. First, wire the controller's abort signal to React cleanup, so navigating away cancels the upstream request instead of paying for tokens nobody will read. Second, keep rendering cheap: append to state on animation frames rather than per token, and if you render Markdown, do it on the completed buffer instead of re-parsing the partial string on every chunk.
Managing prompts, cost, and caching from Node
Prompts live in the repository as versioned files — system prompt, few-shot examples, output schema — and the Express layer selects them by feature name. Two habits keep MERN AI features affordable:
- Cache the stable prefix. System prompt, tool definitions, and reference material sit at the front of every request and are identical byte for byte; only the user turn varies. In a Node service this is easy to enforce because one module builds the payload for every provider.
- Record usage per request. Write input tokens, output tokens, cache hits, and latency to MongoDB with the user and feature attached. Without that table, cost conversations are guesswork.
I also keep conversation history out of the model's context window by default. Rather than re-sending every stored message on each turn, I send a fixed window of recent turns plus a summary document generated when a thread grows past a threshold. That one rule keeps a long chat from quietly becoming the most expensive endpoint in the app, and the same numbers drive model selection here: pick the cheapest model that passes your examples.
Shipping: rate limits, evals, and honest error states
Before a MERN AI feature goes live I want four things in place. Per-user rate limits in Express, backed by a Mongo or Redis counter, so a runaway loop cannot empty your budget. A small eval set — twenty realistic inputs with expected outcomes — run whenever a prompt changes. Structured logs carrying one request ID from Express to the provider response, so a bad output is reproducible. And an error state the UI actually shows: a retry button on timeouts, a plain-language message on rate limits, and a fallback path when the model returns something unusable.
That is also where the rest of the site matters. If your AI feature lives next to marketing pages, the delivery model for those pages has its own trade-offs — I write about them in my Next.js vs React SPA SEO comparison.
FAQ
Do I need to change my MERN app's architecture to add AI features?
Usually not — you add an AI module behind Express and a React view that consumes it. The main structural change is centralizing provider calls in one adapter so keys, retries, prompts, and usage tracking are handled in a single place instead of scattered across routes.
Should the React app call the LLM provider directly?
No. Direct browser calls expose your API key, bypass rate limits and usage logging, and lock your UI to one vendor's SDK. Route every call through Express, where you can authenticate, validate, cache, and meter it.
How do I stream responses with Express and MongoDB-backed chats?
Stream tokens from the provider through Express to the client with a fetch ReadableStream or SSE, then persist the completed message to MongoDB once the stream finishes. Writing partial messages on every chunk creates needless write load and complicates retries.
How do I keep MERN AI features from getting expensive?
Cap output tokens, cache the unchanged prompt prefix, route simple steps to a cheaper model, and log tokens per user and feature in MongoDB from day one. Cost control works best as a persisted metric you can query, not a dashboard you remember to check.
If you have a Node/React app and a feature you think belongs behind a model call, I'm happy to sketch the API shape and the failure modes before any code is written — get in touch and we can map it out.