Applied AI
RAG That Doesn't Hallucinate: Evaluation-First LLM Pipelines
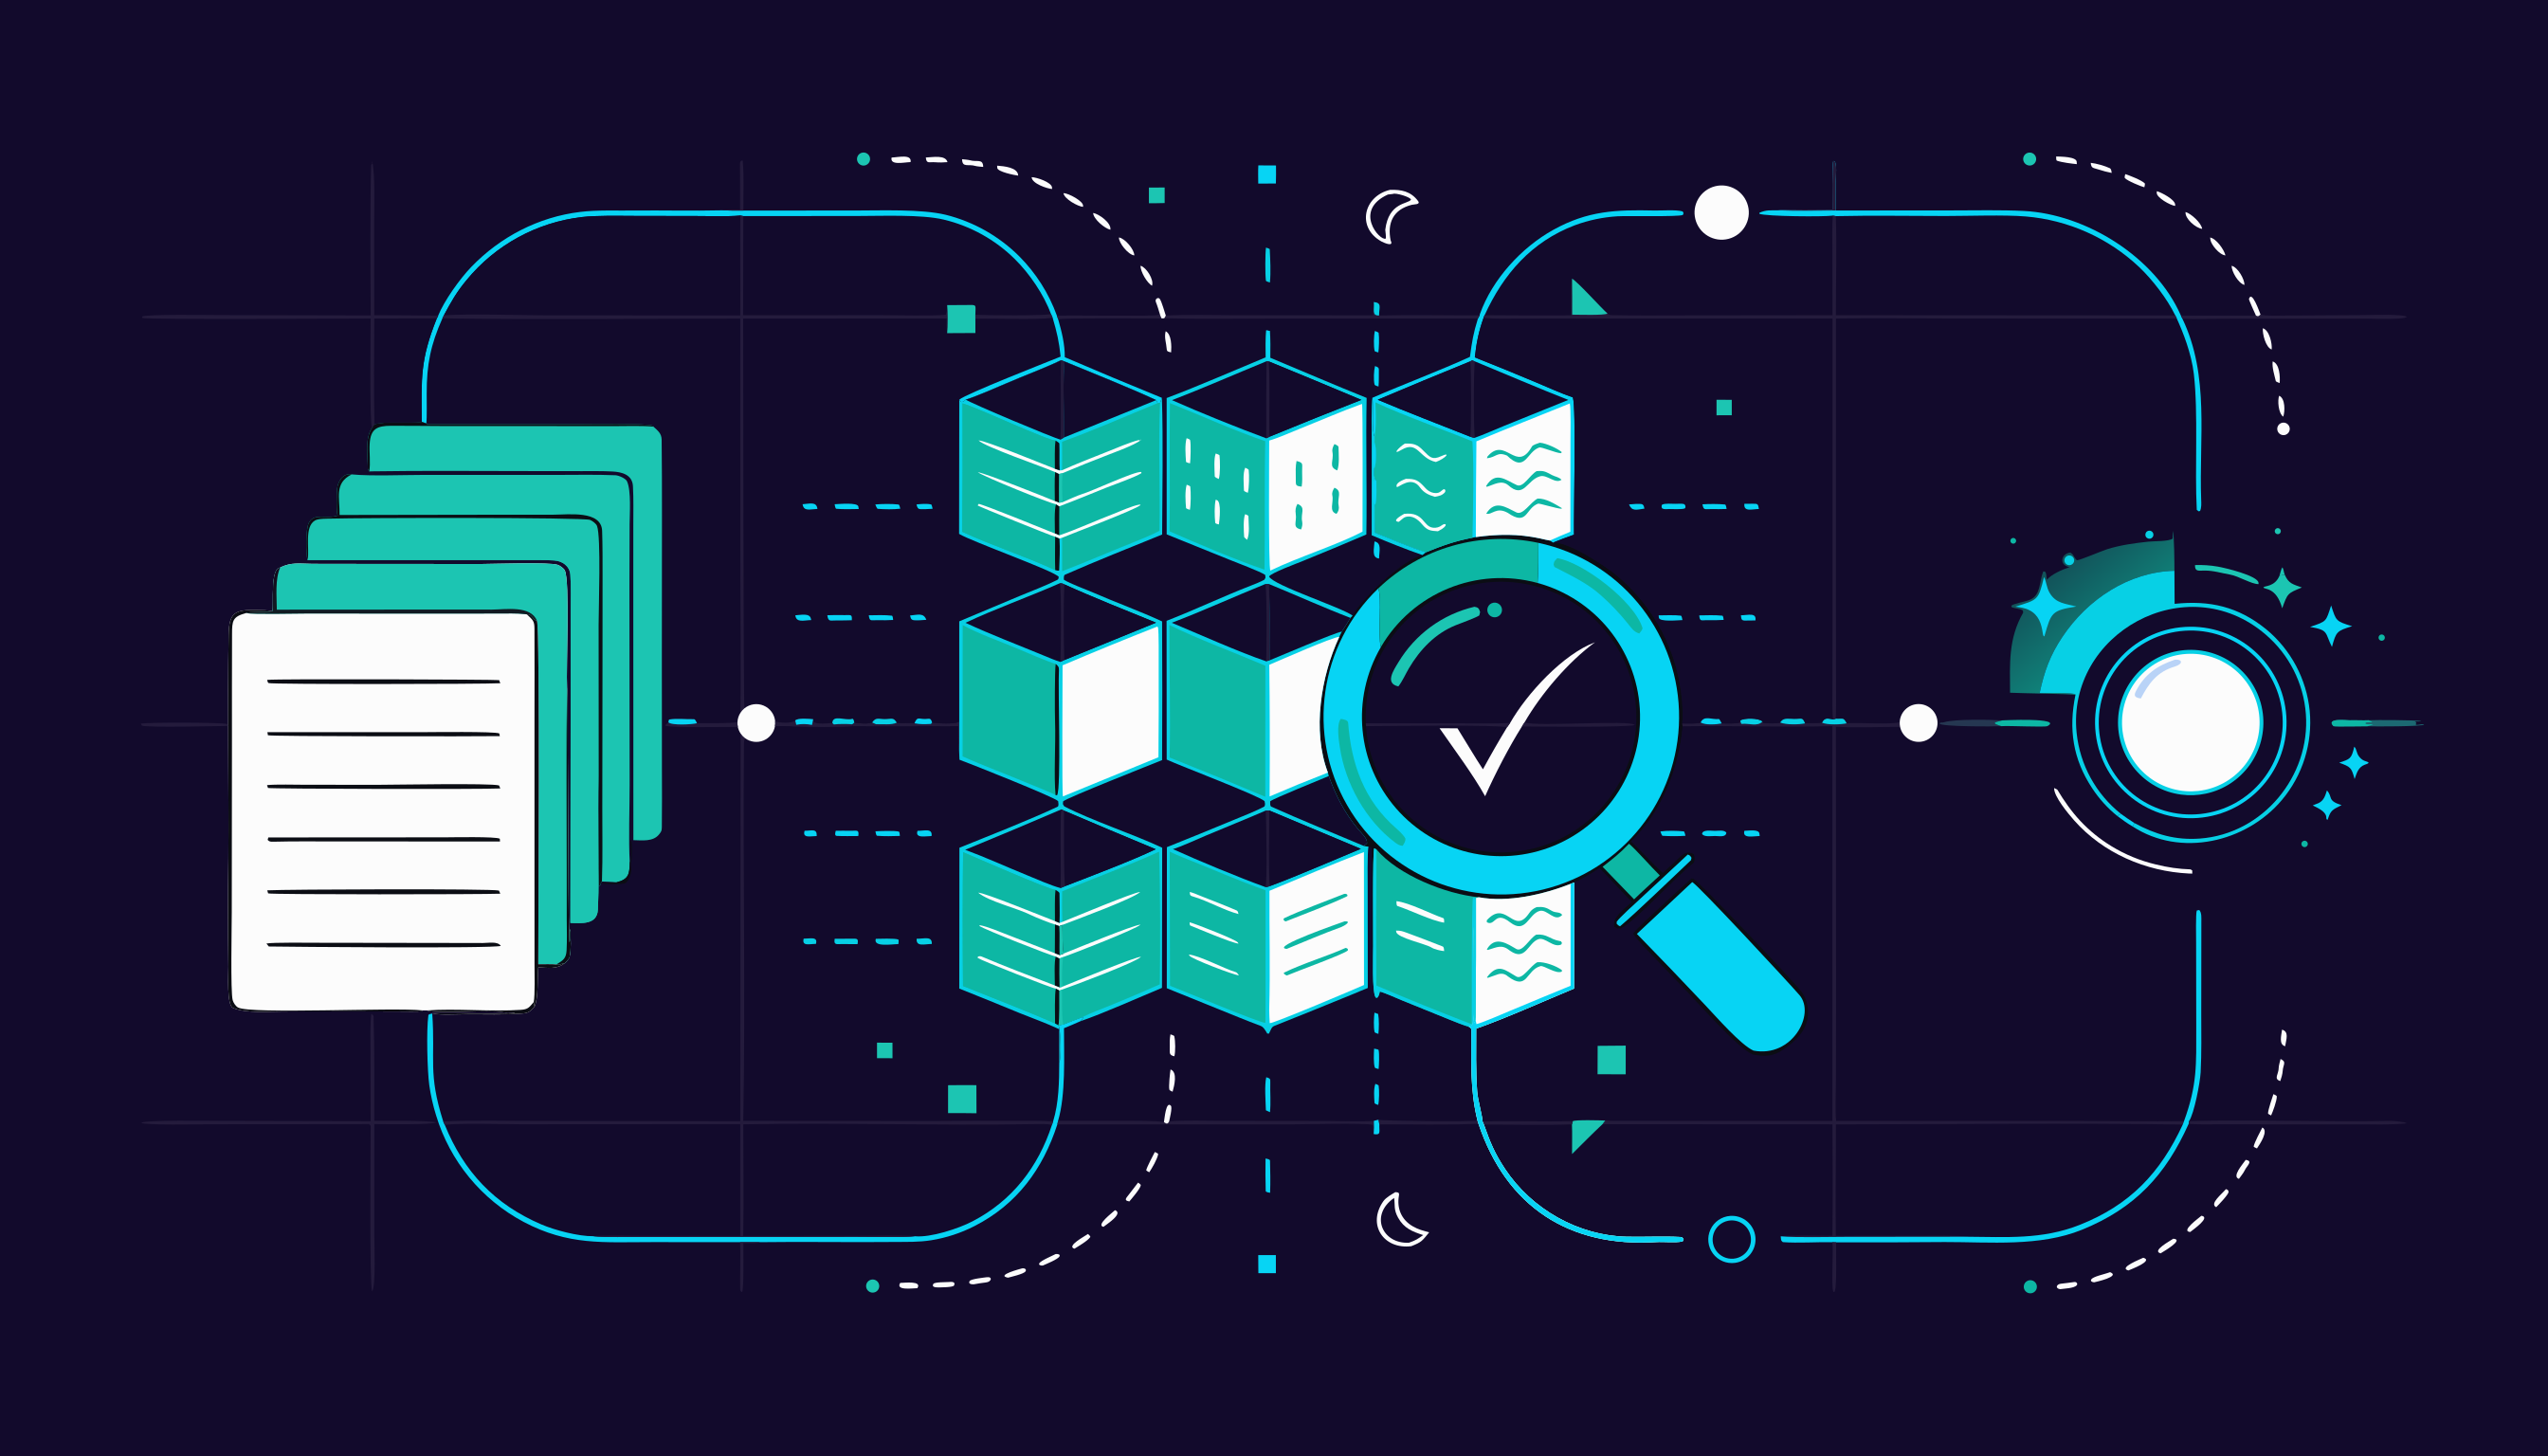
Most RAG projects I see are built backwards: someone wires up a vector database, connects a model, demo it on three questions, and calls it done. Then a user asks the fourth question and gets a confident, sourced-sounding answer that is not in any document. This post is about doing RAG evaluation first — building the evaluation harness before the pipeline — so you can measure whether retrieval and generation actually work instead of arguing about vibes.
I am an Applied AI Engineer based in Dubai, and the pattern below is the one I use on LLM features that have to survive contact with real users: define the eval set, instrument each stage separately, and refuse to tune what you cannot measure.
Why RAG pipelines hallucinate in the first place
Hallucination in RAG is rarely one problem. It is a chain, and the failure usually starts several stages before the model ever runs:
- Retrieval misses the evidence. The right chunk was never in the top-k, so the model answers from priors. No prompt fix recovers a document you did not retrieve.
- Retrieval returns near-misses. The top-k is full of topically similar but irrelevant chunks — a classic failure when queries and documents use different vocabulary.
- Context is packed badly. The answer spans two chunks, only one made it into the window, or the relevant chunk is buried in the middle of a long context.
- The model over-reads the context. It extrapolates past what the passage says, fills gaps, or blends the question's assumptions with the evidence.
- The source is stale or wrong. Garbage in the index still produces fluent answers out of the model.
The reason to evaluate first is exactly this: a single end-to-end score cannot tell you which of those five happened. Stage-level evaluation can, and each one has a different fix.
Build the evaluation set before the pipeline
The eval set is the artifact everything else hangs on, so I build it first, when there is nothing to evaluate yet. What goes in it:
- Real questions, not synthetic ones. Queries from actual users, support tickets, or domain experts — including the messy phrasing people really type.
- Known-answer pairs. For each question, the correct answer and the specific document passages that justify it. This is what makes retrieval measurable instead of anecdotal.
- Deliberate edge cases. Questions the corpus cannot answer (the system must say so), ambiguous questions, multi-hop questions that need two documents, and questions using vocabulary the documents never use.
You do not need thousands of items to start. A few dozen carefully chosen question-answer pairs with gold passages will expose most retrieval and grounding problems, and they are cheap enough to extend over time as real queries come in. The key discipline: the eval set is version-controlled, and it never contains the same examples you use to tune prompts, or you are just measuring overfitting.
The metrics that matter for RAG evaluation
I evaluate each stage with metrics that match its job, then add one end-to-end check:
| Stage | What it answers | Metrics I use |
|---|---|---|
| Retrieval | Did the evidence make it into the top-k? | Recall@k, MRR / nDCG |
| Grounding | Is the answer supported by what was retrieved? | Faithfulness (claims vs. passages) |
| Answer quality | Does it actually answer the question? | Answer relevance, citation accuracy |
| End-to-end | Would a user accept this output? | Task success on the gold set, plus an "abstain correctly" check |
Two properties make these metrics worth the effort:
- They decompose. If faithfulness is high but recall is low, your problem is retrieval, and no amount of prompt rewriting will fix it.
- They are computable automatically. Recall against gold passages is arithmetic. Faithfulness and relevance are usually judged by an LLM-as-judge against explicit rubrics — which itself needs spot-checking, because a lazy judge grades everything as fine.
The abstention check deserves special attention for RAG systems: I include unanswerable questions and score whether the system declines rather than fabricates. A pipeline that answers everything confidently fails this even when its other numbers look healthy.
The pipeline architecture I evaluate against
The concrete shape I run evals over:
- Ingest and chunk — documents split with overlap, structure preserved, metadata attached (source, date, section).
- Embed and index — vectors stored alongside the original text, so every retrieved item carries provenance.
- Retrieve — top-k candidates from a first-pass search, usually hybrid: lexical search for exact terms plus vector search for meaning.
- Rerank — a second pass reorders candidates by actual relevance to the query, which is the cheapest lever I know for near-miss retrieval problems.
- Pack context — passages assembled into the prompt with source labels and clear boundaries between them.
- Generate with citations — the model instructed to answer only from the provided passages and to cite them, making faithfulness checkable automatically.
- Validate and log — schema checks, citation existence checks (does the cited source actually appear?), and full traces of every stage for later analysis.
Because every stage logs its inputs and outputs, a failing eval item can be replayed and inspected stage by stage. That trace is what turns a score into a diagnosis.
Running evals continuously so quality doesn't drift
An eval harness you run once is a photo; you need a video. In practice I wire the eval set into the change process:
- Run it on every prompt, model, chunking, or retriever change. This is the whole point — refactors that "shouldn't change behavior" often quietly do.
- Gate on regression, not vanity. The rule is simple: no merge that lowers retrieval recall or faithfulness on the gold set, even if latency improves.
- Keep a small production sample. Periodically sample real queries, have their answers labeled, and fold the interesting ones back into the eval set. Real traffic finds failure modes that expert-written questions miss.
- Track scores by category — answerable vs. unanswerable, single-hop vs. multi-hop — because an overall average hides exactly the failures users complain about.
What to fix when a score drops
Once evaluation tells you which stage broke, the fixes are mostly unglamorous:
- Low recall — chunk smaller or with better boundaries, add hybrid lexical search, expand queries, or index metadata you were filtering away.
- Good recall, bad ranking — add or retune a reranker; it is usually a bigger win than swapping embedding models.
- Good retrieval, unfaithful answers — tighten the prompt to forbid out-of-context claims, require sentence-level citations, and shorten or restructure the packed context.
- Confident answers to unanswerable questions — add an explicit abstention instruction with a relevance threshold, and include unanswerable examples in the eval set so you can measure it.
- Everything slightly worse after a model swap — check the new model's instruction-following and citation format first; formatting failures often masquerade as quality regressions.
If you are shipping this kind of feature beyond a demo, my notes on LLM production lessons cover the operational side of keeping it stable.
FAQ
How many evaluation examples do I need to start?
A few dozen high-quality question-answer pairs with gold passages will expose the majority of retrieval and grounding problems. Volume matters less than coverage: include unanswerable questions, multi-hop cases, and real user phrasing from day one.
Is LLM-as-judge reliable enough for faithfulness scoring?
It is workable if you give it a strict rubric, score claims individually rather than the whole answer at once, and periodically spot-check its verdicts against your own review. Treat the judge as a noisy instrument you calibrate, or its grades drift toward "looks fine to me."
What is the difference between RAG evaluation and normal LLM evaluation?
RAG evaluation measures two coupled systems — retrieval and generation — so you evaluate them separately as well as end-to-end. Plain LLM evaluation only has the generation side; without retrieval metrics you cannot tell a knowledge gap from a reasoning failure.
Can't I just rely on citations to prevent hallucinations?
Citations make hallucinations detectable, not impossible. You still need a check that cited passages genuinely support the claim — systems that only display citations while skipping that verification inherit all the same failure modes.
If you are standing up a retrieval system and want the evaluation layer designed alongside it rather than bolted on afterward, get in touch and we can scope it together. You can also see selected work for the systems I have shipped.